The starting point
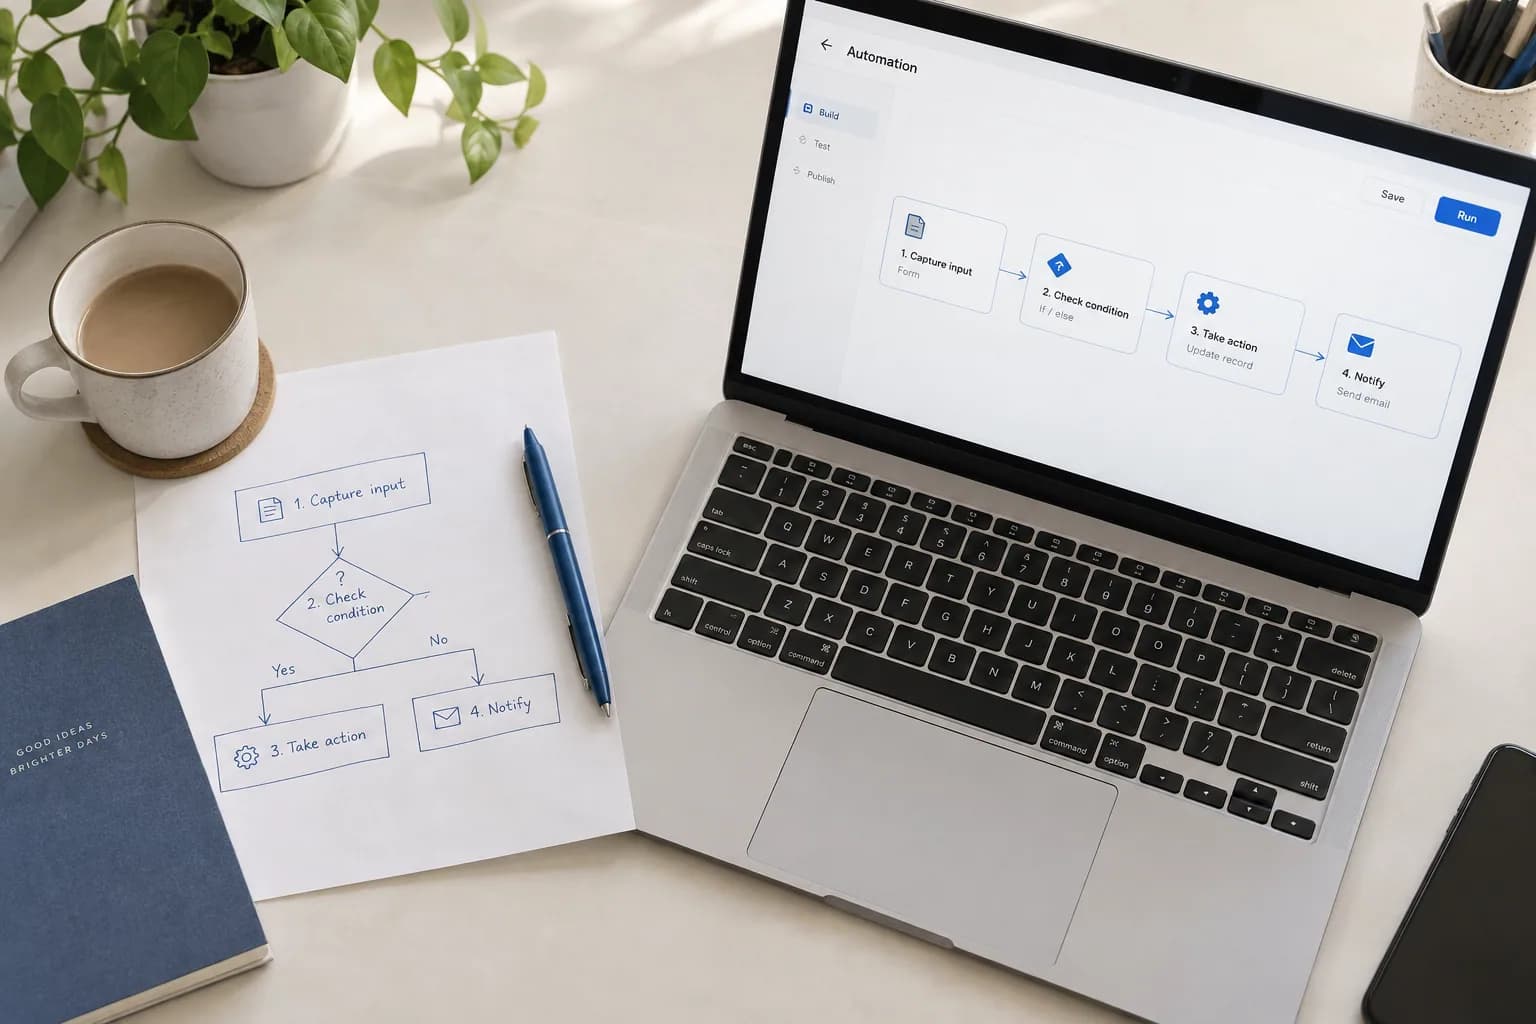
A training project often begins with a folder of documents and an ambitious goal. The useful work starts one step earlier: deciding what the model should do and what a good example looks like. For an illustrative support-ticket classifier, that means agreeing which requests belong in each queue before asking a model to learn the distinction.
Describe the decision you want to improve
Write down the input, expected output and person who will use the result. A ticket classifier needs clear categories and a way to handle requests that fit none of them. A drafting assistant needs examples of the response you want, including its boundaries and tone.
Establish a baseline before planning training. Try the current manual process, a simple rule or an existing model on representative examples. Record where it succeeds and where it fails. The training proposal should address a specific gap, with evidence that the gap matters to the workflow.
Make the examples worth learning from
Review where each example came from, whether it may be used for this purpose and how it was labelled. Remove unnecessary personal information and obvious duplicates. Keep a record of corrections so another reviewer can understand why an example changed.
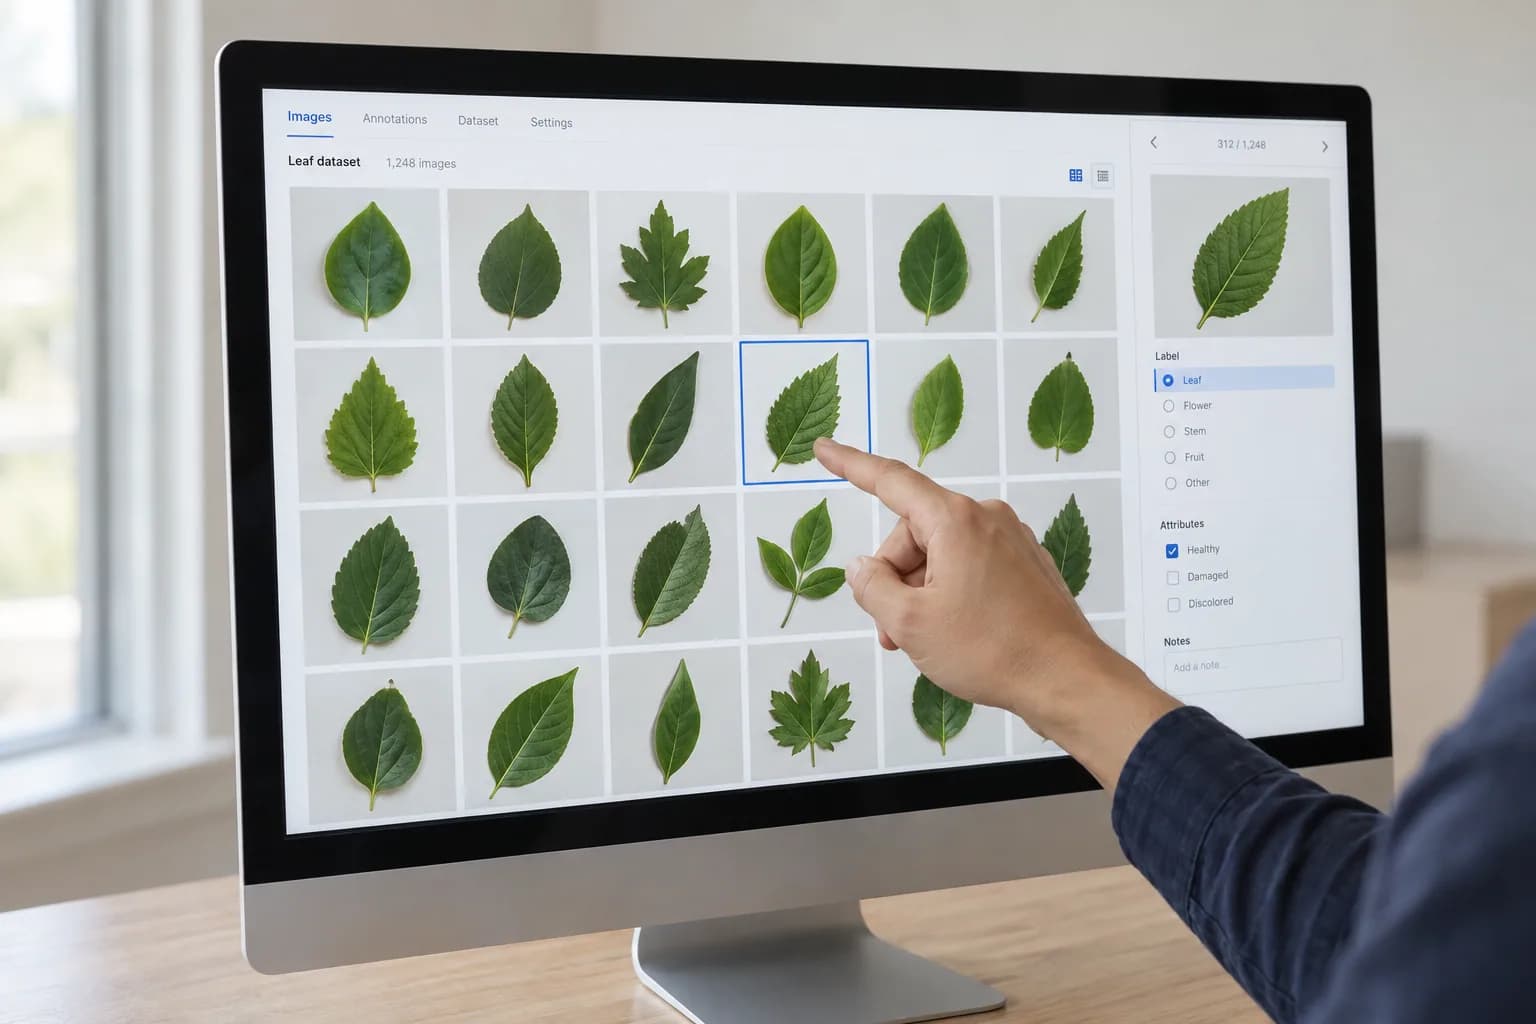
Ask two knowledgeable reviewers to label a small sample independently. Disagreements can reveal an unclear task definition. Resolve those disagreements in a shared guide before expanding the dataset. Include unusual but relevant cases instead of collecting only the easiest examples.
Keep an independent check on progress
Separate the examples used for training, validation and final testing. Google's Machine Learning Crash Course explains these different roles: learning from one set, tuning against another and checking the final result on held-out data. Repeatedly tuning to the final test set weakens that independent check.
Agree the evaluation criteria before reviewing the results. For a ticket classifier, examine which queues are confused and what those mistakes would mean for the receiving team. A single headline score can hide the exact failure that makes the system unsuitable for a particular workflow.
Treat deployment as the next experiment
Record the dataset version, training configuration and evaluation results alongside each candidate. Compare them with the baseline, including review effort and operating costs. Keep the option to stop or use a simpler approach when the evidence does not justify the added complexity.
Before integration, decide who reviews uncertain results and how users report mistakes. Name the owner responsible for monitoring changes in incoming data. A model handover should include examples of known limitations and a clear decision about when retraining is worth considering.
Further reading on the distinct roles of training, validation and test data.
Google: Dividing a datasetPut the thinking into practice
Ready for your next step?