AI Workflows & Agentic AI / Case study
micro1.
Evaluating AI where real work happens.
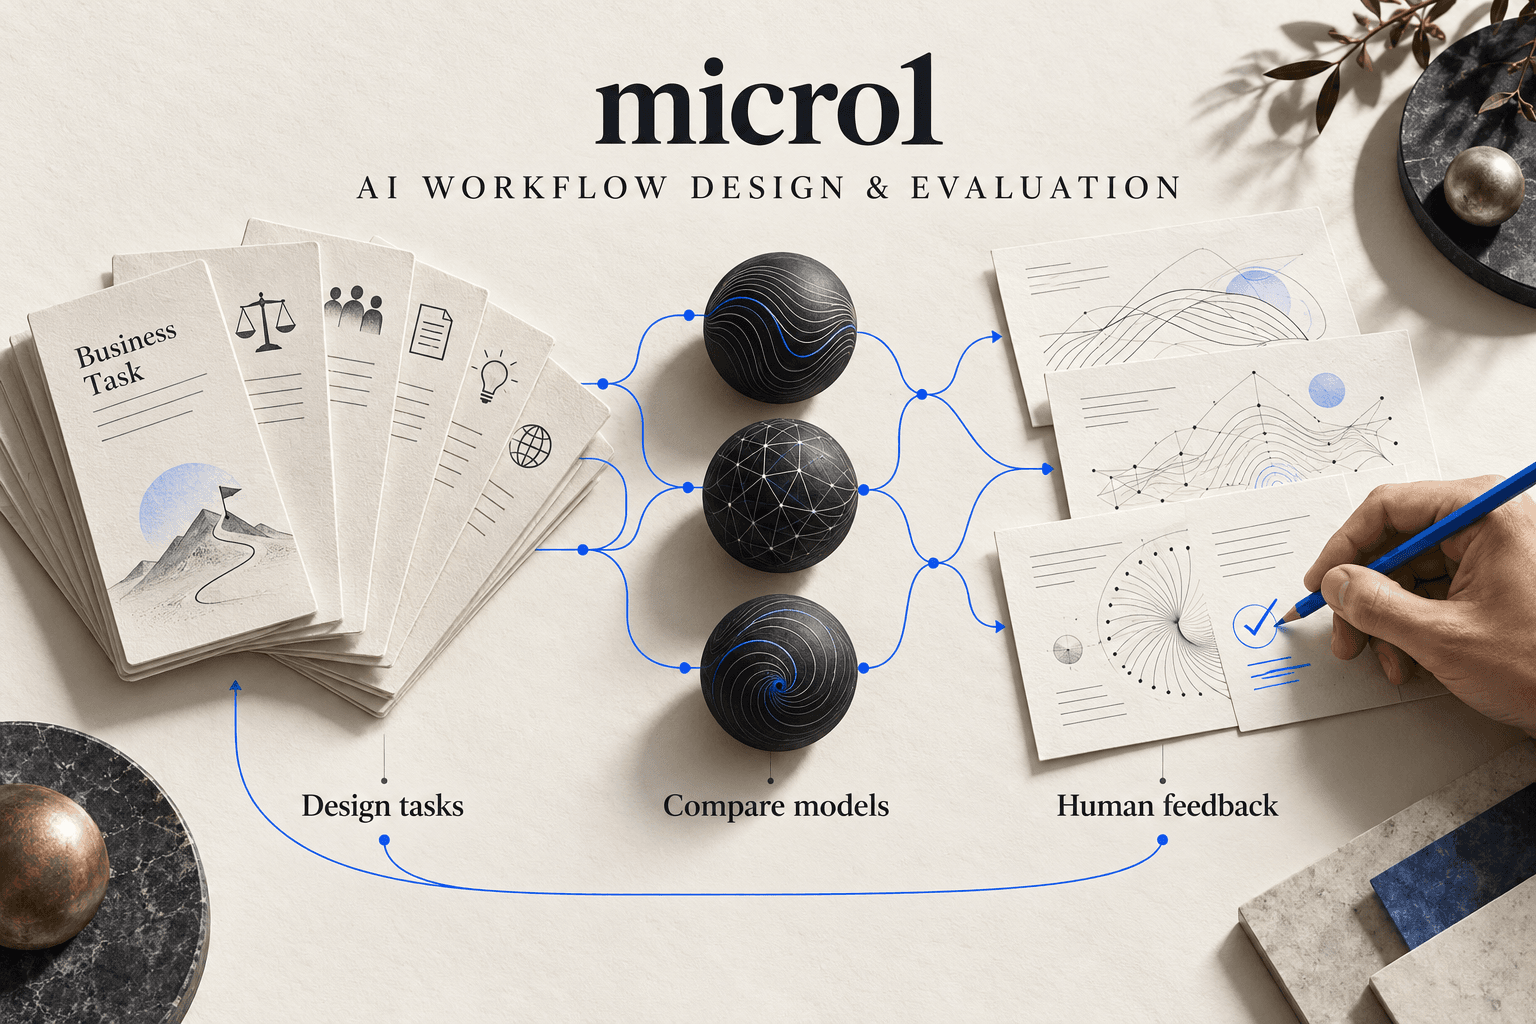
100+ real-world workflows designed, executed and evaluated across AI models, with structured human feedback grounded in business needs.
- The challenge
- micro1 needed realistic business workflows to test models beyond isolated questions and answers. Each task had to reflect practical operations while remaining clear enough for consistent evaluation across models.
- Our contribution
- Engross worked as a dedicated workflow evaluation team: researching business scenarios, writing detailed instructions, executing tasks, comparing model outputs and providing structured human feedback against micro1’s evaluation guidelines.
- The outcome
- 100+ business workflows created and evaluated, supported by a repeatable research, execution, review and refinement process. The engagement gave micro1 practical evaluation scenarios and human feedback to support model improvement.
- Technology & tools
- ChatGPT Pro · OpenAI Codex · Feather Evaluation Platform · Custom workflow templates
What the work involved
- Research business scenarios and define complete, multi-step tasks.
- Create workflow instructions and evaluation scenarios.
- Execute tasks across models and compare their responses and actions.
- Identify quality issues and provide structured human feedback.
- Review and refine workflows against client-defined quality requirements.
From business requirement to evaluation
- Business scenario
- Workflow design
- Model execution
- Model comparison
- Human evaluation
- Structured feedback
- Refinement
Business workflows covered
- Pre-sales
- Post-sales
- Bookkeeping & finance
- HR & internal operations
- SMB business operations
How quality was evaluated
- Accuracy
- Does the result correctly address the task?
- Instruction following
- Does execution follow the workflow requirements?
- Completeness
- Are all required parts of the task covered?
- Business relevance
- Is the result useful in a real business setting?
- Reasoning & quality
- Is the approach logical and reliable?
- Consistency
- Are results dependable across model runs?
Structured feedback supported model improvement and ongoing workflow refinement, with people evaluating the usefulness of the work.